The Surprising Effectiveness of Deleting Weights in LLM Post-Training
Office hours are over for this professor
The US is winning the AI race. Jensen Huang could have blown it
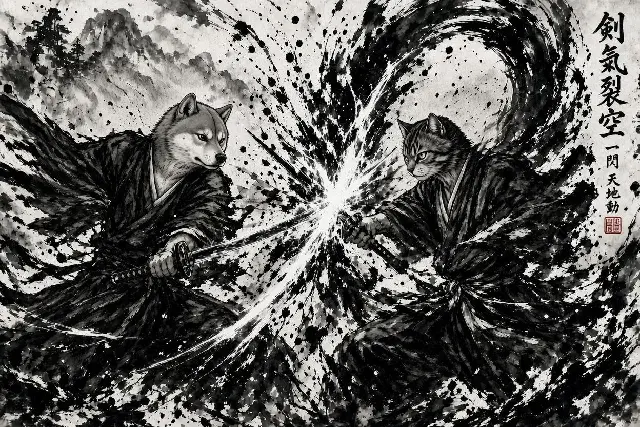
One bright burst between two masters
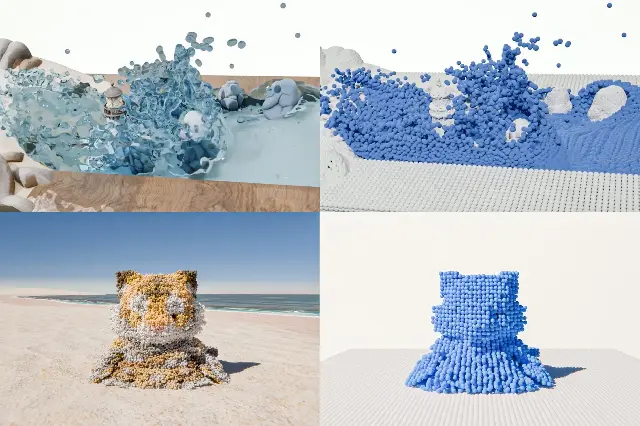
The sand cat came from the same model
Tech companies face mounting child safety lawsuits while pushing AI into schools
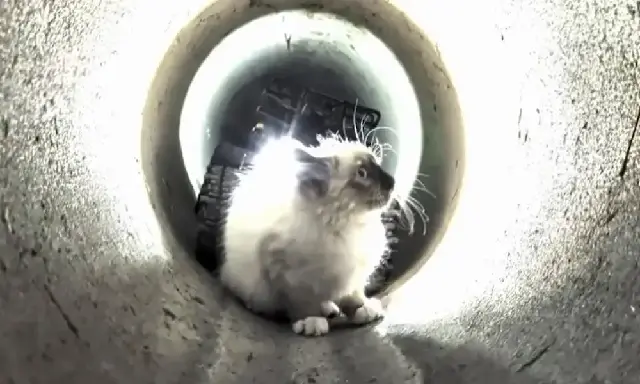
The robot got the kitten out
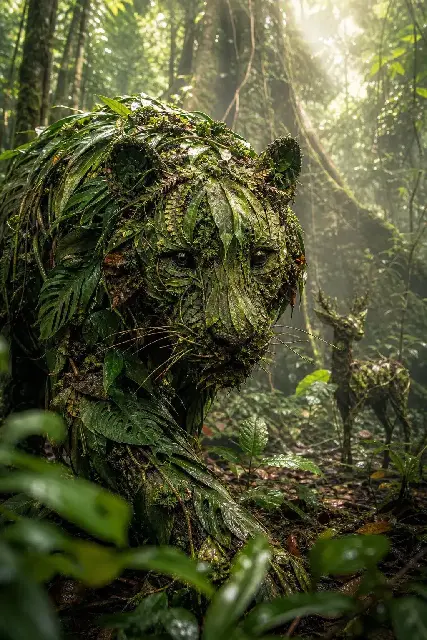
The leaves grew into a lion
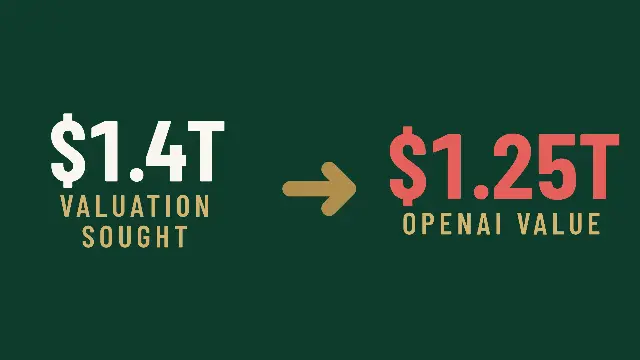
OpenAI Raises $11B at a $1.25T Valuation
Elvis and Eminem rights holders are suing Suno
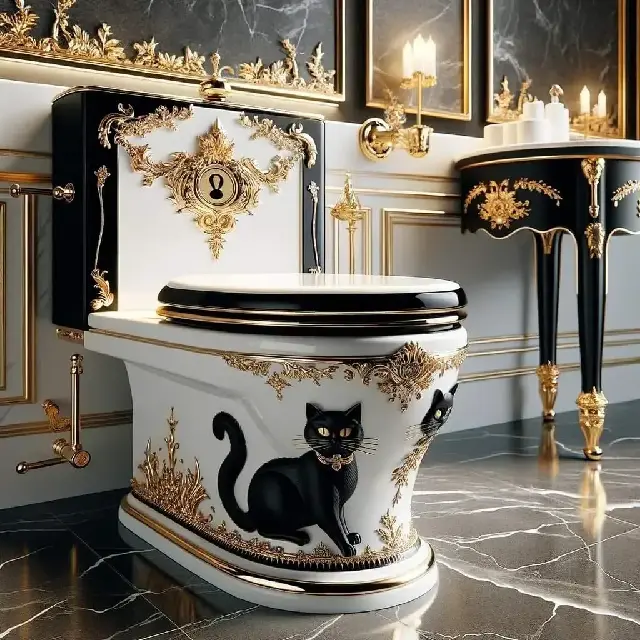
Even the toilet has a cat on it
Why a new report on Anthropic automating AI development is alarming researchers
Leading AI models are biased against certain accents when scoring interviews, presentations and tests
0 replieswashington.edu ↗
Investors brace for lower Anthropic valuation, calling $1.5 trillion a 'stretch'
3 allegedly used AI to steal some $129 million from companies by impersonating executives and lawyers
OpenAI pledges to pay for data center power after election highlights AI concerns
OpenAI is stepping back from NDAs for data center projects
Geoffrey Hinton: it might turn out we were better off without AI
0 repliestheguardian.com ↗
OpenAI hires former U.S. Army Secretary Dan Driscoll for national security role
Anthropic IPO filing: $1.7B quarterly payroll, about $107K per employee monthly
DeepSeek V5 is planned to be pre-trained on Huawei Ascend chips.
A Reddit post links to a STAR Market Daily report that DeepSeek V5 is planned to be pre-trained (trained on large amounts of data before any later tuning) on Huawei Ascend chips, according to industry supply chain…
0 repliesmp.weixin.qq.com ↗
New York Democrats Plan AI Limits in 2027
A study found a chatbot that speaks naturally is more likely to be perceived by users as intelligent and useful, even if it spouts nonsense. These language models still tend to run wild with so-called
OpenAI pitches data center power plants as a way to protect nearby areas
Over 10% of factual claims in Google’s AI search summaries aren’t backed by their cited sources, study finds
China's First Frontier AI Export Controls: Mofcom Announcement No. 48
0 replieslabs.cloudsecurityalliance.org ↗
A cat made entirely of fractals
Cohere Says Alibaba’s Qwen Model Tried to Upload a File to a Beijing Server
0 repliestechnology.org ↗
AI startup hacks Anthropic, gains access to employee details, internal messages
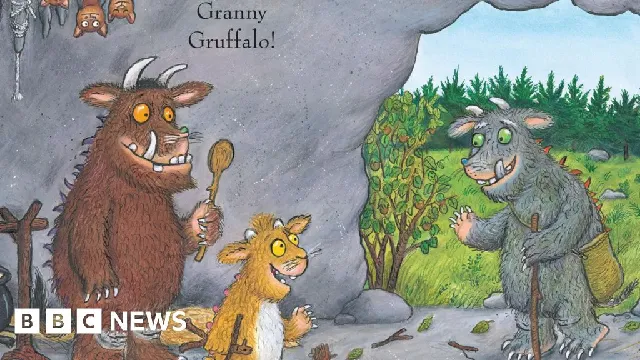
Gruffalo illustrator considering legal action against AI firms
 The Surprising Effectiveness of Deleting Weights in LLM Post-TrainingHow little of a pretrained large language model (LLM) has to change for it to acquire new capabilities? We find that zeroing fewer than 0.05% of its weights, with no other modification, matches full…
AI LLMs that see every letter: Most LLMs never see the individual letters of a word directly. A new method changes that by retrofitting existing models at a fraction of the usual training cost
EmbeddingGemma 2: a best-in-class open model for natively multimodal embeddings
mistralai/Mistral-Large-4-1T-A52B
Cerebras Deploys Trillion-Parameter AI Models
Muse Spark Open